The image is saved at outputs/Qwen_image_2.1_00002.png. It is 3:2 landscape and took about 175 seconds. The seed was 895035350286699.
Prompt used: I expanded your idea into one English paragraph. It keeps your details exactly: a red vintage bicycle, an old brick wall, late-afternoon light, a quiet small-town European street, photographic style, landscape, and no text. I added these details myself, because you left them open:
- Cobblestones.
- A step-through frame, curved handlebars and a leather saddle.
- The bicycle placed slightly left of center.
- Side light with long shadows.
- Shallow depth of field.
Workflow changes: I changed only three values.
- The prompt text in node
459:474.on_false. The workflow's prompt-rewriting switch is off, so this is the text that reaches the model. I left the switch off. - A random seed in the KSampler.
- The aspect ratio, set to "3:2 (Photo)". Your workflow has no plain "landscape" choice. I picked 3:2 over 16:9 because it suits a photographic look.
The model, steps, sampler and everything else are as in your file.
Does it match? Yes, closely, from looking at the picture.
- Bicycle: A red vintage step-through bicycle leans against a brick wall. It has a brown leather saddle, curved handlebars and spoked wheels. It reads as a vintage city bike.
- Wall and street: The wall is old, weathered brick with patches of ochre plaster. The street is narrow and cobbled, with old buildings with barred windows receding into a blurred background. It looks like a small European town, Italian in feel, and it is empty and quiet.
- Light: It is warm and golden, with side light raking across the bricks. It reads as late afternoon.
- Style: It looks like a photograph, with shallow depth of field and natural texture.
- Text: I see none.
Minor caveats:
- The bicycle is lit only softly, and the strongest light is on the wall behind it. The cobbles in front are fairly dark, so I don't see the long cast shadows I asked for.
- The bicycle's rear section and rack are slightly muddled, which is typical of AI-generated bicycles. It is fine at this size but may show up if you zoom in.
If you want stronger golden light on the bicycle itself or clearer cast shadows, I can add that to the prompt and run another seed.
Test run on my own ComfyUI 0.39.2 (macOS, Apple Silicon), with the Qwen Image 2.1 text-to-image workflow, prompt rewriting left off. The picture was generated for real in about 175 seconds and I looked at it myself: it matches the request, with softer light and fewer long shadows than asked and a slightly muddled rear of the bicycle. The image itself is not embedded here. An earlier attempt was cancelled by me part-way and is not counted. The tester's local server and models are needed to repeat it.
它做什麼
把「想要一張圖」的需求變成由你本機 ComfyUI 產生的圖片。它先檢查服務(版本、裝置、佇列),以及你的工作流程能不能執行:它用到的每種節點、每個模型檔或選項都必須存在,否則就停下並明確說缺什麼,不會替你換模型。接著它找出提示詞、種子與尺寸在工作流程裡的位置,把一個簡短的想法擴寫成清楚的提示詞,同時保留你固定的細節(必須出現的文字、數量、顏色),先用試跑驗證一切,再提交任務、等待、儲存 ComfyUI 產生的圖片,並親自看一眼結果,告訴你哪些符合、哪些不符合。模型與風格來自你提供的工作流程。
輸出
你指定資料夾裡的圖片檔、使用的提示詞與種子、工作流程裡改動過的值,以及對圖片的如實核對。
使用前準備
- ComfyUI 必須已經在執行,並且你的工作流程已儲存為 API 格式。
- 請先把工作流程用到的所有模型檔下載好(主模型、文字編碼器、VAE 以及用到的 LoRA),放進 ComfyUI 對應的模型資料夾。這個 Skill 只會檢查它們是否存在,缺了就停下,但絕不會下載任何東西。
- 較新的模型可能用到只有新版 ComfyUI 才有的節點。如果檢查提示缺節點,請先更新 ComfyUI。
測試環境
ComfyUI 0.39.2,macOS 15.3,Apple M4 Max,64 GB 統一記憶體(MPS 裝置)。工作流程:Qwen Image 2.1 文生圖,關閉了它自帶的提示詞改寫。模型:qwen_image_2.1_int8_convrot(主模型)、qwen3vl_8b_int8_convrot(文字編碼器)、qwen_image_2.1_vae_bf16(VAE)。一張 3:2 的圖約 175 秒。其他工作流程沒有測試。
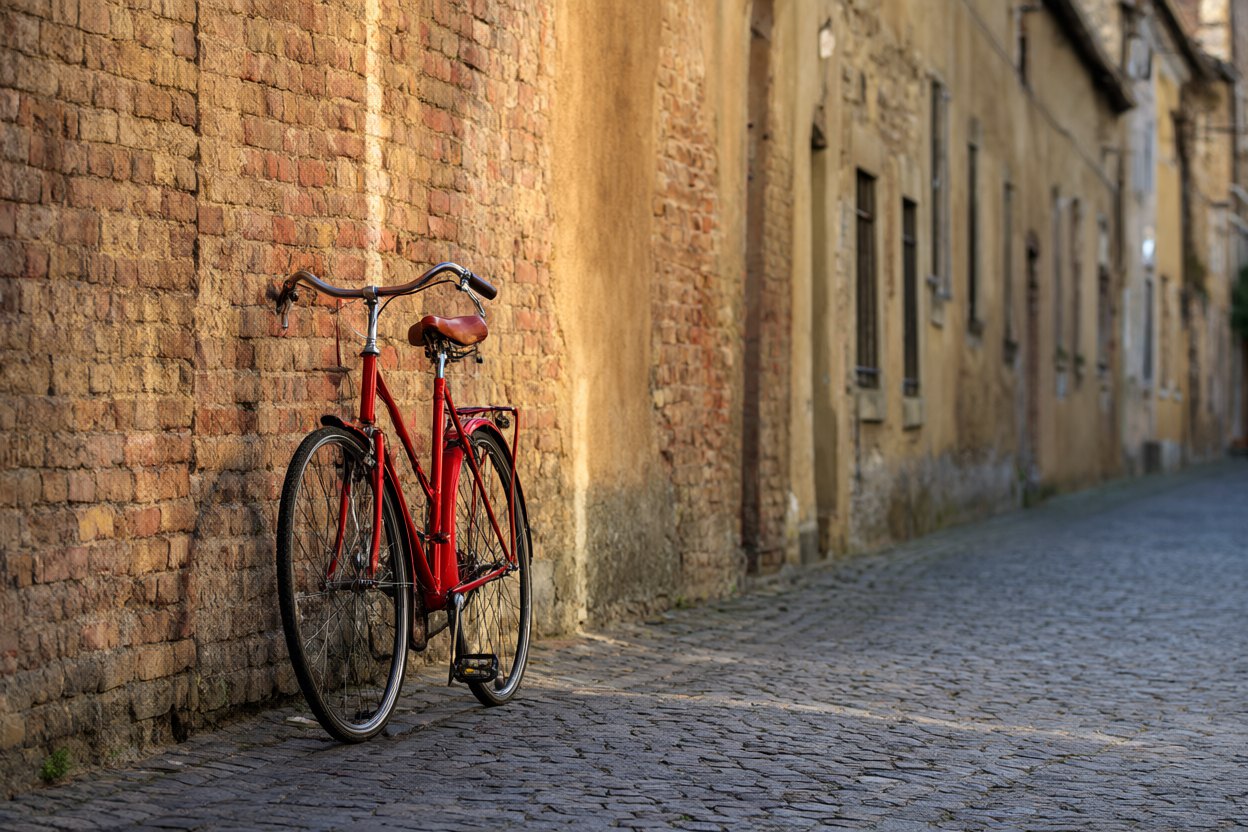
測試中產生的圖片:Qwen Image 2.1,3:2,25 步,種子 895035350286699,約 175 秒。下面的提示詞是智能體根據一句話需求寫出來的;圖片保持產生時的樣子,沒有修圖。
A photograph of a red vintage bicycle leaning against an old, weathered brick wall on a quiet cobblestone street in a small European town. The bicycle stands slightly left of center, filling about a third of the frame, with a classic step-through frame, curved handlebars and a leather saddle. Low late-afternoon sun comes from the side, casting warm golden light and long soft shadows across the bricks and cobbles; the muted ochre and terracotta wall contrasts with the saturated red of the bicycle. Empty street with softly blurred old buildings in the background. Natural documentary photography, shallow depth of field, landscape composition, no text, no signs, no lettering.
適合什麼場景
已經在用 ComfyUI、想讓智能體寫提示詞、執行工作流程並回報結果的人。需要 ComfyUI 正在執行,以及儲存為 API 格式的工作流程。
中風險:需要你自己的 ComfyUI。它包含一個 Python 腳本(只用標準函式庫),連線 127.0.0.1 的 ComfyUI,遇到其他位址會拒絕,除非你明確允許;ComfyUI 沒有登入,請不要把它暴露到網路上。它不會啟動或停止服務,不安裝節點、不下載模型,只把圖片檔寫進輸出資料夾。一次任務會佔用你的 GPU 與記憶體數分鐘。已在 macOS 上用 Qwen Image 2.1 真實試用:約 175 秒產生了一張符合要求的圖,圖片本身沒有放在示範裡。請先下載好工作流程需要的所有模型,Skill 只檢查、絕不下載。僅在 ComfyUI 0.39.2 與 Qwen Image 2.1 工作流程上測試過。AIBars 原創(MIT)。